Ship agents that survive production.
Inferloom is the workflow platform for LLM agents — build visually, evaluate against real traffic, trace every hop, and deploy in one command.
Trusted by teams shipping agents at
The platform
Everything between a prompt and a reliable agent.
A visual builder, an evaluation loop, tracing, and deploys — wired together so "it worked in the notebook" keeps working in prod.
Visual flow builder
Compose agents from typed nodes — retrieval, tools, routers, graders. Version, diff and roll back flows like code.
Evaluation loop
Turn real production traces into datasets. Score with LLM graders and heuristics, gate deploys on regressions.
Full-fidelity tracing
Every prompt, tool call, token and latency, stitched into a replayable trace. Find the hop that broke — fast.
One-command deploys
Ship a flow as a versioned HTTP API with streaming, retries and rate limits. Preview environments per branch.
Guardrails & fallbacks
Schema-validate outputs, cap spend, and fail over across models and providers without touching your code.
MCP & tool registry
Register MCP servers and internal tools once. Connect them to any flow with scoped, auditable credentials.
How it works
From first node to first customer in an afternoon.
Build on the canvas
Drag nodes, wire tools and retrieval, and preview against a prompt set. Nothing to install locally.
Evaluate & harden
Replay real traces, add graders, and watch pass-rate and cost before you expose anything to users.
Deploy an endpoint
Promote the flow and call it over HTTP. Tracing, evals and rollbacks apply automatically.
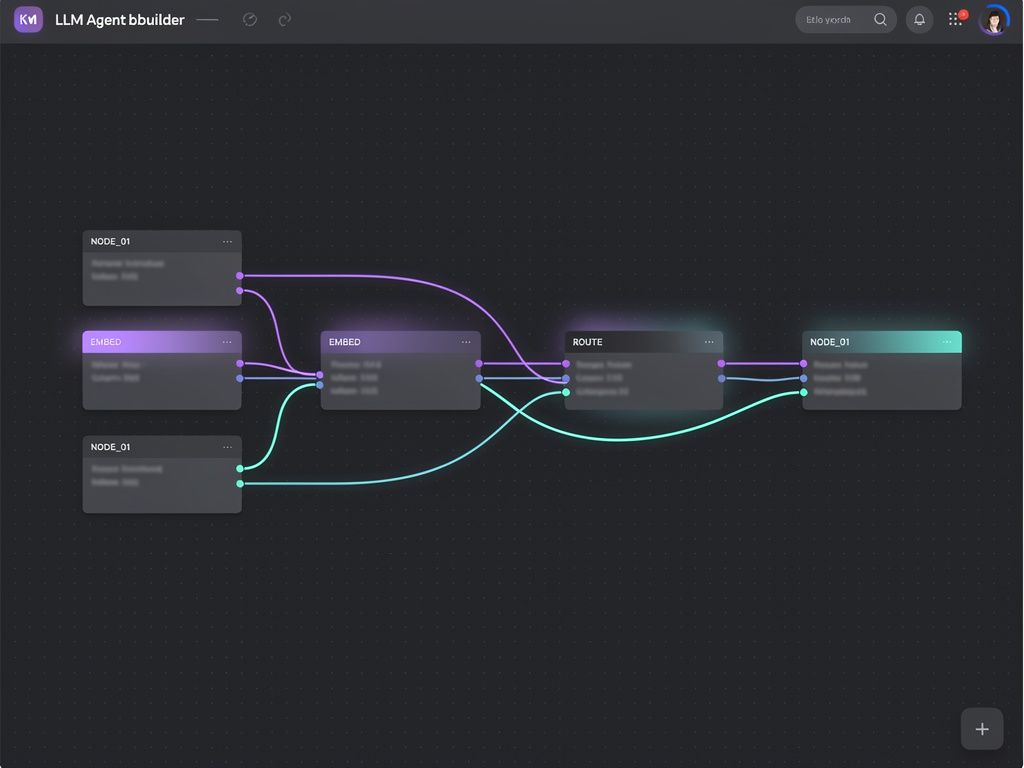
Versioned by default. Every flow is a git-like lineage — diff, promote, roll back.
Type-safe nodes. Inputs and outputs are validated, so wires can't silently break.
Preview environments. Each branch ships its own URL for stakeholders to poke at.
Observability
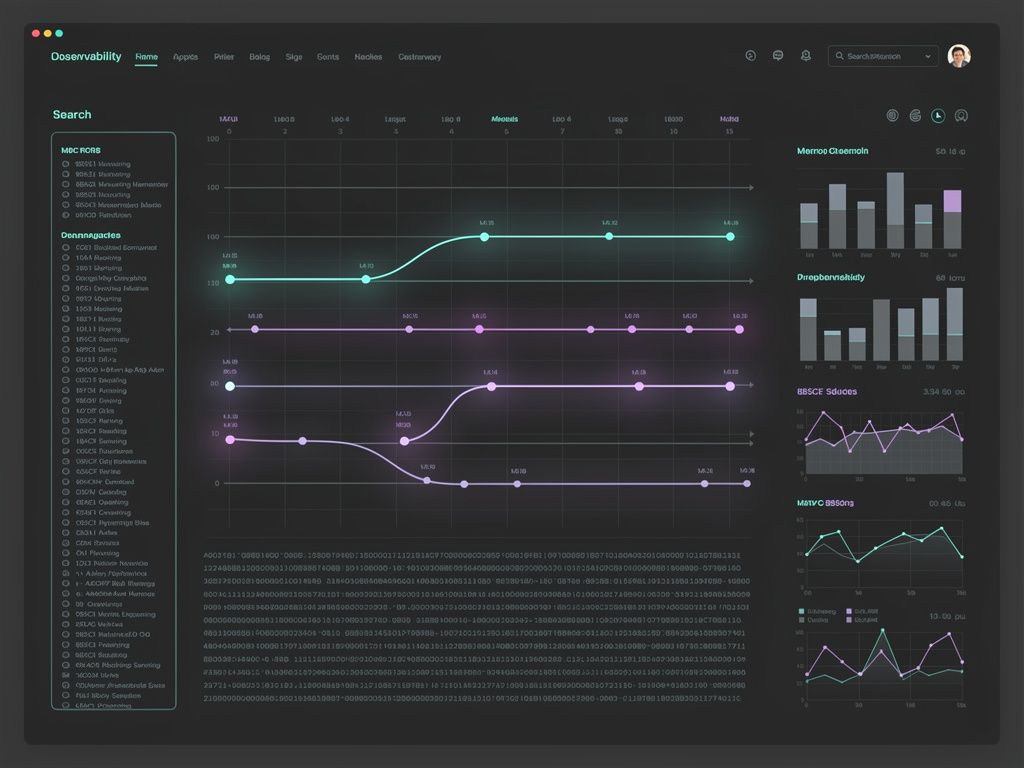
If it happened in prod, you can replay it.
Traces, evals and cost live next to each other. Sample, filter, and turn any interesting session into a regression test in two clicks.
Integrate
Call a flow like any other API.
Deployed flows are OpenAI-compatible by default, with streaming, structured outputs and usage in the response.
SDKs for Python, TypeScript and Go — or plain curl.
Webhooks and background runs for long-horizon agents.
OpenAPI schema and a full interactive reference.
# deploy a flow, then call it
curl https://api.inferloom.dev/v1/chat/completions \
  -H "Authorization: Bearer $INFERLOOM_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "flow": "customer-support-agent",
    "messages": [{ "role": "user", "content": "Where is order #1042?" }],
    "stream": true
  }'
from inferloom import Client

client = Client()  # reads INFERLOOM_API_KEY

run = client.flows.run(
    "customer-support-agent",
    messages=[{ "role": "user", "content": "Where is order #1042?" }],
)
print(run.output, run.trace_url)
import Inferloom from "@inferloom/sdk";

const client = new Inferloom();

const run = await client.flows.run("customer-support-agent", {
  messages: [{ role: "user", content: "Where is order #1042?" }],
});
console.log(run.output);
Pricing
Start free. Pay when it works.
Usage-based on runs and tokens, with generous free tiers. Annual billing saves two months.
For prototypes and side projects.
- 10k runs / month
- 3 flows, 14-day traces
- Community support
For teams putting agents in front of customers.
- 500k runs / month
- Unlimited flows, 90-day traces
- Evals, guardrails, preview envs
- Email support (1 business day)
For high-volume and regulated workloads.
- Usage-based runs, SSO/SAML
- EU residency, custom retention
- 99.9% SLA, dedicated support
“We replaced three internal tools with Inferloom. Our on-call pager for the agent team basically went quiet.”
“The eval loop is the killer feature. Every incident becomes a test before lunch.”
“Deployed our support agent in a day, and we actually understand every hop it takes.”
FAQ
Questions, answered.
Which models and providers do you support?
Inferloom is provider-agnostic: OpenAI, Anthropic, Google, Mistral, and any OpenAI-compatible endpoint — including self-hosted. Swap models per node and fail over automatically.
Do you train on my data?
No. Your prompts, traces and datasets stay yours. EU data residency and configurable retention are available on Scale.
Can I self-host?
Yes — a single container runs the whole control plane, with Postgres and Redis as the only external dependencies. Air-gapped installs are supported.
How is pricing metered?
A "run" is one flow invocation, regardless of how many nodes it executes. Model tokens are billed at cost plus a small margin shown up-front.
Is there a free trial of Pro?
Every workspace starts on Pro for 14 days, no card required. Downgrade to Hobby automatically if you don't upgrade.
Get started
Weave your first agent today.
Free forever for prototypes. Open the Studio, build a flow, ship an endpoint — all before your coffee goes cold.